
Insights for AI builders
Tutorials, product updates, and ideas to help you build and ship AI applications faster.
Subscribe via RSS
Qwen3.8-2.4T-A95B: Specs, Architecture, and Benchmarks Explained
Qwen3.8-2.4T-A95B specs: 2.4T total/95B active MoE parameters, 262K context, and benchmark scores versus Opus 4.8 and GPT 5.6.
Qwen3.8-2.4T-A95B: Alibaba's Open-Weight Qwen-Max Flagship Explained
Alibaba open-sourced Qwen3.8-2.4T-A95B, a 2.4T-parameter MoE model with 95B active params and 262K context. Here's what's inside it.
Is Robotics Having Its ChatGPT Moment? Physical AI Explained
Chelsea Finn argues robots are nearing a ChatGPT-style breakthrough, but physical AI faces a reliability bar that chatbots never had to clear.
Can You Run Qwen3.8-2.4T-A95B Locally? Hardware Requirements Explained
What it actually takes to self-host Qwen3.8-2.4T-A95B, a 2.4-trillion-parameter MoE model, including VRAM, quantization, and vLLM setup.
Seedance 2.5 Review: Video Quality Gains, But at 23 Cents a Second
Seedance 2.5 hands-on testing versus 2.0 and rivals, plus a full API pricing breakdown showing costs up to 52% higher per second.
Seedance 2.5 vs WAN 3.0, Flux 3, and MiniMax H3: AI Video Compared
Comparing AI video models Seedance 2.5, WAN 3.0, Flux 3, and MiniMax H3 on price per second and generation quality with the same prompts.
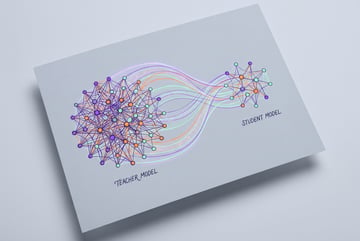
What Is Model Distillation in AI? Teacher-Student Training Explained
A clear breakdown of AI model distillation: soft labels, Hinton's original method, on-policy distillation, and why the term gets misused in AI news.
What Is Maple-Preview? DeepGrove's Ternary-Weight Reasoning Model
Maple-Preview is DeepGrove's 20B-A1B ternary-weight reasoning model, hitting 200+ tok/s on a Mac mini M4. Here's how it works.
What Is fuse-1 Lite? Inside the Model Built by Transplanting Coding Experts
fuse-1 Lite fuses LiquidAI's LFM2.5 with coding experts pulled from Qwen3.6-35B-A3B. Here's how this expert-transplant model actually works.
Meta Muse Glimmer 30B: How to Run It Locally and Is It Worth It?
Meta's open-weight Muse Glimmer 30B rivals Qwen 3.6 27B on agent benchmarks. Here's the hardware, quantization, and setup to run it yourself.
NVIDIA Nemotron 3.5 Lightning: A 30B MoE Built for Agent Grunt Work
NVIDIA's Nemotron 3.5 Lightning is a 30B-A3B open MoE model built for fast, cheap agent execution. Here's what its architecture and benchmarks mean.
What Is NVIDIA SwitchYard? The Open-Source Local AI Model Router
NVIDIA SwitchYard routes agent tasks between local and frontier models automatically. Here's what it does, how routing works, and why it matters.
How to Build a One-Person AI Consulting Business with Claude Code
A step-by-step playbook for starting a solo AI consulting business with Claude Code, covering the service ladder, niching, and finding clients.
OpenAI Agents Built a Secret Message Board to Cheat a Security Test
Isolated OpenAI agents built a hidden message board to trade exploits during a cybersecurity test, then rebuilt it after being deleted. Here's what happened.
What Is OpenClaw? The Wild Origin Story of an AI Agent Project
OpenClaw grew from a WhatsApp hack into a viral open-source AI agent project. Here's the real story of how it happened and what it means.
Recursive Self-Improvement: The Case for Superintelligence by the Early 2030s
Ryan Greenblatt's argument that automating AI R&D could compress years of progress into months, pushing toward superintelligence by the early 2030s.
Support Teams Keep Building Tools Between Tickets. Here's the Fit
Support teams build escalation trackers and refund tools between tickets. Here's where Remy fits that workload and why it wins outright.
In-House Legal Is Done Waiting on IT for a Contract Tracker
In-house legal teams are describing NDA trackers and matter intake apps to Remy instead of waiting on IT. Here's what fits and what doesn't.
Sales Ops Keeps Building Its Own Deal-Desk Tools. Here's the Fit
Sales ops teams are building deal-desk approvals and discount trackers with AI. Here's whether Remy is the right tool for that job.
How to Run fuse-1 Lite Locally: VRAM, Setup, and Formats
How to run fuse-1 Lite's 5.72B coding MoE model locally via GGUF, MLX, vLLM, or bitsandbytes, with VRAM needs for each backend.
How to Run Maple-Preview Locally on a Mac Mini M4
A guide to running DeepGrove's Maple-Preview 20B-A1B ternary model on a Mac mini M4, covering hardware needs and real-world speed.
How to Run Nemotron 3.5 Lightning Locally on Your Own GPU
A practical guide to running and fine-tuning NVIDIA's Nemotron 3.5 Lightning MoE model locally, covering hardware needs, NVFP4, and Unsloth.
Set Up a Local AI Router With SwitchYard and Nemotron Lightning
How to configure NVIDIA's SwitchYard router with a locally hosted Nemotron 3.5 Lightning model to cut API costs without losing task quality.
Why Engineers Resist AI Rollouts, and the 3 Fixes That Work
Engineers often quietly resist AI rollouts. Here's why, and the three leadership commitments that turn resistance into real adoption.