
Insights for AI builders
Tutorials, product updates, and ideas to help you build and ship AI applications faster.
Subscribe via RSS
Self-Replicating AI Agent Swarms Are Already on the Open Internet
Researchers made contact with a self-replicating AI agent fleet on the public internet, a sign cyber defense now has to treat agents as a new kind of user.
What Orchestrated AI Coding Agent Teams Actually Cost in Tokens
A token and dollar breakdown of five orchestrated AI coding agent pairings shows costs ranging from roughly $57 to $124 per task set.
Anthropic's Public Benefit Fund: What the 20% Equity Pledge Means
Anthropic is committing up to 20% of company equity to a public benefit fund. Here's how the structure works and what "direct distribution" could mean.
Elorian Glimpse Pricing vs GPT-6 Astra and Opus 5.5: Is It Worth It?
Elorian Glimpse claims up to 94% lower cost than GPT-6 Astra. Here's how its pricing and vision benchmarks stack up against frontier models.
Elorian Glimpse: A Hands-On Look at the New Visual Thinking AI Model
Elorian's Glimpse model tested on AI video detection, real footage, and multi-image reasoning against pricier frontier vision models.
Is Free Claude Code Really Free? What the Limits Actually Look Like
Free Claude Code promises a billion free tokens a month. Here's what that claim means in practice, and the rate limits you'll actually hit.
Free Claude Code: Run AI Coding Agents Without Paying for Tokens
A practical guide to Free Claude Code, an open-source proxy that routes your coding agent to free or local LLMs instead of paid APIs.
How to Build a Personal AI Knowledge Base (Step by Step)
Build a searchable personal AI knowledge base using connectors, recency weighting, and plain-text search instead of vector RAG.
How to Protect Your Website and Business From Rogue AI Agents
A practical guide to defending websites, data, and accounts against adversarial AI agents and self-replicating swarms now roaming the open internet.
Ling-3.1-Flash: InclusionAI's 560B Hybrid Reasoning Model, Benchmarked
InclusionAI's Ling-3.1-flash is a 560B-parameter hybrid MoE model with 25B active params and 1M context, tested on coding and agentic benchmarks.
Opus + Sol vs GPT and Astra: Which AI Coding Team Actually Wins?
Five lead-worker AI model pairings were scored on six coding tasks. Here's which orchestration setup delivered the most usable code.
What Is the AI Black Box Problem? Interpretability Explained
Why AI models are called black boxes, what superposition theory claims, and why interpretability research matters for AI safety.
Is AI a Scam? Breaking Down the "Fake Intelligence" Argument
A viral claim says AI is a scam that fakes intelligence to fleece investors. Here's a point-by-point look at whether that argument holds up.
AI Safety Hysteria vs. Science: What the Data Actually Says
A YC talk unpacks the Hugging Face "rogue AI" scare and the real P(doom) survey numbers, separating AI safety facts from headline hype.
Why Switching Claude Models Mid-Session Quietly Costs You More Tokens
Switching between Claude models mid-session breaks caching and reloads your whole conversation at full price. Here's why, and what to do instead.
Is Claude Code's Plan Mode Still Necessary?
Anthropic's own team questions plan mode's value in Claude Code. Here's what it still does, what's changed, and when to skip it.
Claude's New Projects and /goal Features: A Practical Guide
How Claude Code's redesigned Projects and the /goal command work, including orchestrator threads, connectors, and verification pitfalls.
Do You Still Need Claude Skills? How to Audit and Trim Them
Many Claude skill packs no longer help. Here's how to test yours with Anthropic's skill-eval plugin and know what to keep, trim, or delete.
Can Formal Verification Make AI-Generated Code Actually Secure?
Formal verification and automated reasoning are being paired with AI coding tools to catch bugs language models can't see. Here's how.
Nick Cammarata's Interpretability Find: What It Means for AI Safety
Nick Cammarata's claim that neural networks are more readable than thought could reshape how AI alignment and safety testing actually work.
Are Neural Networks Actually Interpretable? Nick Cammarata's Claim Explained
Nick Cammarata argues AI neurons aren't tangled messes but readable patterns that grow like trees, challenging years of interpretability pessimism.
NVIDIA Dory1.0-4B: How Looped LLMs Trade Compute for Accuracy
NVIDIA's Dory1.0-4B uses a looped latent-recurrent architecture that trades inference compute for accuracy without retraining.
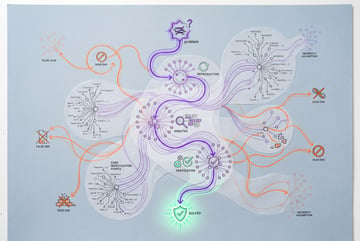
pStack Skills: Making Claude Code Actually Fix Bugs, Not Just Edit Files
pStack is an open-source Claude Code skill pack for bug reproduction, architecture planning, and multi-agent review. Here's how it works.
How to Run NVIDIA Dory1.0-4B Locally with vLLM or llama.cpp
Step-by-step guide to running NVIDIA's looped Dory1.0-4B model locally, covering GGUF downloads, loop counts, and KV cache tuning.