SenseNova-Loop-9B-Preview: Inside the Looped Transformer You Can Run Now
SenseNova-Loop-9B-Preview reuses 24 layers twice for 56 decoder executions from 32 stored layers. Specs, setup, and deployment explained.
What is SenseNova-Loop-9B-Preview?
SenseNova-Loop-9B-Preview is an open-weight multimodal model released by SenseNova that reuses a block of decoder layers twice during inference instead of storing separate weights for every layer. It has 32 distinct decoder layers but performs 56 layer executions per forward pass, because layers 4 through 27 run, then run again with the same weights before the final layers and output head finish the job. The model takes text and images as input and produces text, and it’s built for long-context and agentic workloads, with documented training sequences up to 262,144 tokens.
TL;DR
- Looped execution means SenseNova-Loop-9B-Preview computes 56 decoder-layer passes from only 32 stored layers, by running layers 4 to 27 twice with shared weights.
- Two-stream mHC (manifold-constrained hyper-connections) manages how information flows between two residual streams inside the looped section, using Sinkhorn normalization with 20 iterations to constrain the stream-mixing maps.
- Parameter count sits at roughly 9B stored parameters but behaves like a ~14.6B model at inference time, since the repeated block effectively doubles compute without doubling memory.
- Hybrid attention alternates three linear-attention layers with one full-attention layer in a repeating four-layer pattern, and loop boundaries always align with complete four-layer groups.
- Deployment options already exist through Hugging Face Transformers, LightLLM, and a SGLang pull request, so you don’t need custom inference code to try it.
- MTP (multi-token prediction) is available now for faster inference, while two other acceleration methods, Dspark and Dflash2, are still in training.
- The license is Apache 2.0, and the checkpoint ships with full safetensors weights split across eight shards plus a dedicated MTP weights file.

How does the looped transformer architecture work?
Most transformer models run each layer exactly once per forward pass: data flows in at layer 0 and out at the final layer, touching every set of weights a single time. SenseNova-Loop-9B-Preview breaks that pattern for one segment of the network.
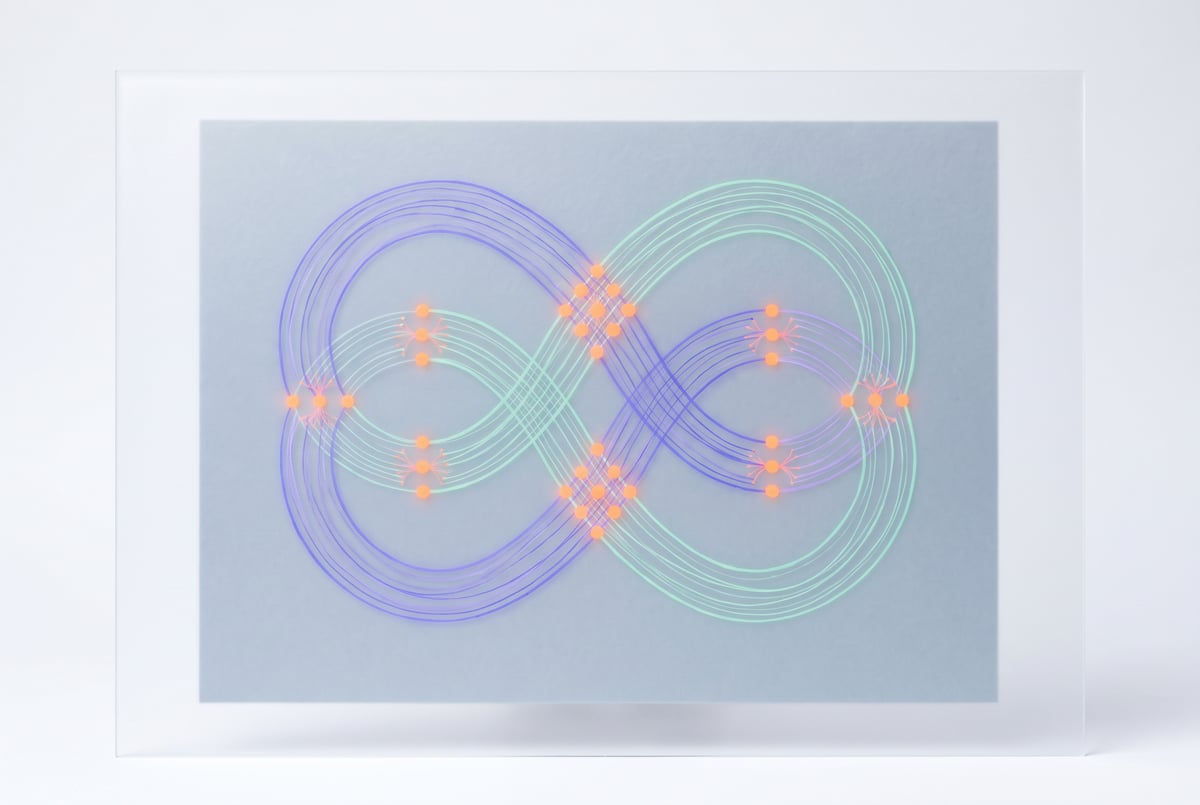
The model has 32 distinct decoder layers total. Layers 0 through 3 run first, as a normal entry block. Then layers 4 through 27, a 24-layer block, run through the network twice in sequence, reusing identical weights for both passes. The model card expresses this with a simple formula: if B is the repeated block and h is its input, the looped computation is B(B(h)). After the second pass, layers 28 through 31 and the output head finish the forward pass.
The arithmetic works out to 56 total decoder-layer executions (4 + 24 + 24 + 4) from only 32 stored sets of weights. That’s the core trade the architecture makes: more effective depth and compute per token, without a proportional increase in parameter count or memory footprint. It’s why the model card lists both a backbone scale (~9B total parameters) and a separate inference parameter estimate (~14.6B), since the second pass through the shared block adds compute that a parameter count alone doesn’t capture.
What is mHC and why does it matter here?
Running the same block of layers twice creates a technical problem: if you just feed the output of the first pass straight back in as input to the second pass, you risk losing information or creating representations that don’t compose well across iterations. SenseNova’s answer is two-stream manifold-constrained hyper-connections, or mHC.
Instead of one residual stream carrying information through the looped layers, there are two. Learned mappings control three things: how each layer reads from the two streams, how it mixes information between them, and how it writes its own output back into the residual state. The stream-mixing map is constrained using Sinkhorn normalization, run for 20 iterations in the documented configuration. This keeps the mixing well-behaved rather than letting the two streams diverge or collapse into redundancy over repeated passes.
Practically, this means a compatible inference engine can’t just load the weights and run them like a standard transformer. It has to also load the mHC routing parameters and reproduce the same two-stream execution order, which is why the model ships custom modeling code (modeling_sensenova_loop.py) rather than relying solely on a generic Transformers architecture class.
What does the hybrid attention pattern look like?
Layered on top of the looping is a mixed attention design. The decoder interleaves linear-attention layers with full-attention layers in a fixed rhythm: every group of four layers contains three linear-attention layers followed by one full-attention layer. The model card specifies 16 full-attention heads and 4 KV heads, a hidden dimension of 4,096, and a feed-forward dimension of 12,288.
Without shadow IT.
The loop boundaries are designed to respect this grouping. Layers 4 through 27 constitute six complete four-layer groups, so looping that block twice preserves the same linear/full attention ratio across both passes rather than cutting a group in half. This matters for anyone trying to reason about compute cost: the expensive full-attention layers are a known, fixed fraction of total executions, not something that shifts depending on where in the stack you measure.
What are the actual specs?
| Property | Value |
|---|---|
| Distinct decoder layers | 32 |
| Decoder-layer executions per pass | 56 |
| Looped layer range / passes | layers 4-27, 2 passes |
| Hidden dimension | 4,096 |
| Feed-forward dimension | 12,288 |
| Vocabulary size | 248,320 |
| Full-attention heads / KV heads | 16 / 4 |
| mHC streams / Sinkhorn iterations | 2 / 20 |
| Training context length | up to 262,144 tokens |
| Export precision | BF16 backbone, FP32 mHC routing |
The weights are distributed as eight safetensors shards plus a separate mtp.safetensors file for the multi-token-prediction head, alongside the usual tokenizer, chat template, and config files needed for a Transformers-based load.
How do you run SenseNova-Loop-9B-Preview locally?
The model loads through Hugging Face Transformers using trust_remote_code=True, which pulls in the custom SenseNova Loop modeling code bundled in the repository. The documented environment uses Transformers 5.18.0 and PyTorch 2.11.0 with CUDA 13.0.
A minimal setup:
python -m pip install "transformers==5.18.0" accelerate safetensorsThen in Python:
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "sensenova/SenseNova-Loop-9B-Preview"
device = "cuda:0"

tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    trust_remote_code=True,
    dtype=torch.bfloat16,
    device_map={"": device},
).eval()
From there, you build a prompt with apply_chat_template, tokenize it, and call generate(). The chat template supports a enable_thinking flag; set it to True to turn on a reasoning mode, or leave it False for direct answers. This single-GPU path is the simplest way to confirm the model runs before moving to a serving stack.
What deployment options exist beyond a single script?
For anything beyond local experimentation, two serving frameworks already have SenseNova Loop support documented:
LightLLM offers a Docker-based four-GPU deployment. Pull the ghcr.io/modeltc/lightllm:main image, mount your local model directory, and launch the API server with tensor parallelism set to 4 (--tp 4). The container exposes an OpenAI-compatible chat completions endpoint on port 8000.
SGLang support currently lives in an open pull request (#47281) rather than a mainline release. Running it means cloning the SGLang repo, fetching that specific PR branch, and installing from source before serving the model with sglang serve --model-path.
For fine-tuning, SenseNova points to a fork of torchtitan with a dedicated training script for mHC and looped execution (mhc2_loop2_titan.sh), runnable on a single 8-GPU node against a JSONL SFT dataset. A separate SenseSpec repository handles training draft models for the two in-progress acceleration methods, Dspark and Dflash2.
Is the looped architecture actually faster or better?
The model card frames the looped design as a way to get more effective depth and reasoning capacity without inflating the parameter count you have to store and load. Whether that translates into better real-world results depends heavily on the task. SenseNova published benchmark comparisons against other models across tasks including BIRD-Dev (database querying), WorkBuddy Bench, AIDABench, TeamBench, Terminal Bench 2.1, T³-Banking, AutomationBench, and RaccoonPPTBench (presentation generation), positioning the model for agentic and document-heavy workflows rather than as a general chat replacement.
Built like a system. Not vibe-coded.
Remy manages the project — every layer architected, not stitched together at the last second.
On raw inference cost, running 56 layer executions instead of 32 means more compute per token than a same-sized non-looped model, even though memory footprint stays closer to a 9B model. The MTP acceleration method is available now to offset some of that cost; Dspark and Dflash2, both still in training as of the release, are meant to provide further speedups once ready. The model card is explicit that practical speedups vary by workload, hardware, and serving configuration, so anyone evaluating this for production should benchmark their own case rather than extrapolate from published numbers.
Frequently Asked Questions
What does “looped transformer” mean in this context?
It means a contiguous block of decoder layers executes more than once per forward pass, reusing the same weights each time rather than running through a chain of entirely distinct layers. In SenseNova-Loop-9B-Preview, layers 4 through 27 run twice, producing extra compute depth without extra stored parameters.
How many parameters does SenseNova-Loop-9B-Preview actually have?
The stored backbone is about 9 billion parameters, but because the looped block runs twice, the effective inference compute is closer to what a 14.6 billion parameter standard model would require.
What is mHC and do I need to understand it to use the model?
mHC (manifold-constrained hyper-connections) is the mechanism that manages two residual information streams through the looped layers using learned, Sinkhorn-normalized mixing maps. You don’t need to understand the math to run the model via Transformers, LightLLM, or SGLang, since the routing logic is baked into the checkpoint and loaded automatically with trust_remote_code=True.
Can I fine-tune SenseNova-Loop-9B-Preview myself?
Yes. SenseNova documents a training path through a forked torchtitan repository with a script specifically built for the mHC and double-loop configuration, runnable on a single 8-GPU node with a custom SFT dataset in JSONL format.
Is SenseNova-Loop-9B-Preview free to use commercially?
The model is released under the Apache 2.0 license, which permits commercial use, modification, and redistribution, subject to the standard terms of that license.