How to Use Evals to Pick the Cheapest AI Model That Works
Learn how to build evals that find the cheapest AI model that meets your business requirements, before you pay for a frontier model you don't need.
What are evals, and why do they determine which AI model you should pay for?
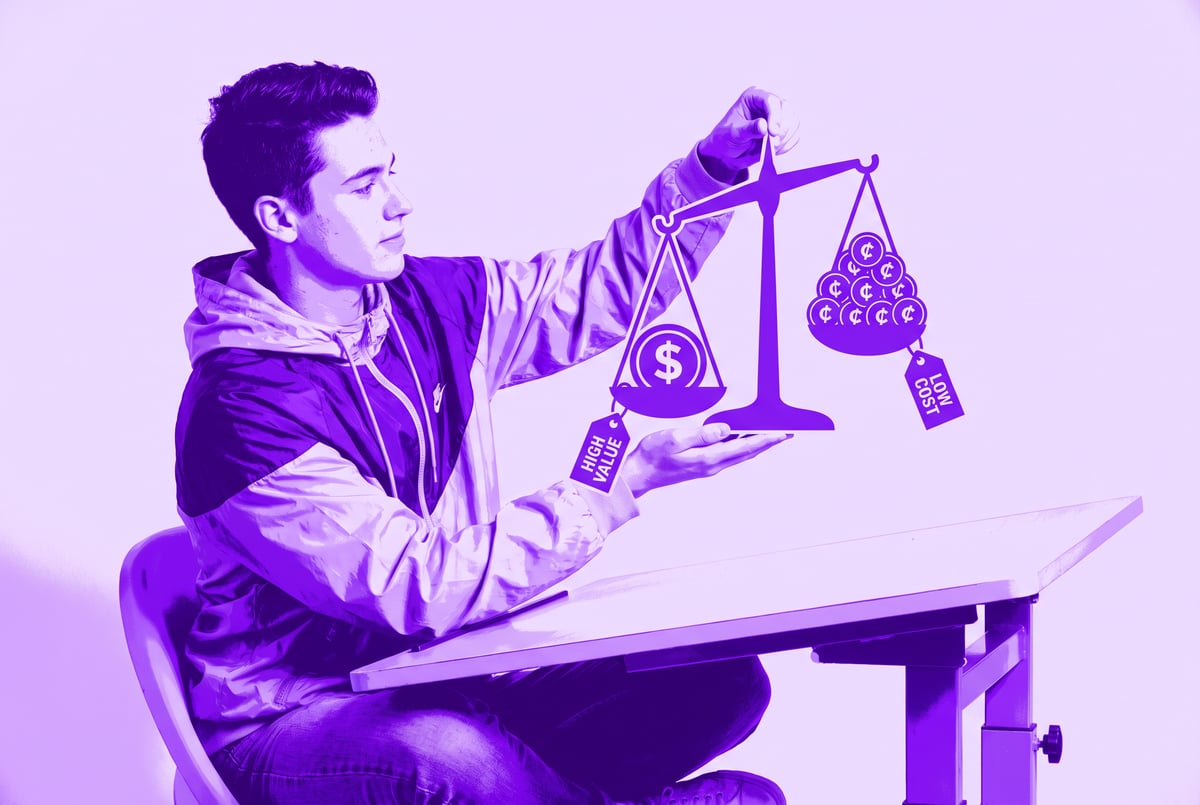
An eval is a test of the actual work you need done, scored against a standard you define as acceptable. Instead of asking “which model is smartest,” you ask “which model, at the lowest price, clears the bar I set for this task.” That shift matters because many business tasks are already task saturated: several models can do the job well enough that paying more for extra intelligence adds little or nothing to the outcome. Evals are how you find out where that saturation point sits for your own workload, rather than guessing from a benchmark leaderboard.
TL;DR
- Evals replace guesswork by testing a cheaper model against the exact work you need done, not against generic benchmarks, so you get evidence instead of a hunch about whether the upgrade is worth it.
- Task saturation means many jobs, like routine customer support replies or routine code edits, are already handled well by inexpensive models, so buying more intelligence doesn’t improve the result.
- Token usage and spend are decoupling: companies can run far more AI workload through cheaper models without their bill going up, because the price per token drops faster than usage rises.
- Procurement teams are using eval results as negotiating power, pushing for discounts on frontier contracts even when they stick with the same vendor, because they can prove a cheaper tier meets requirements.
- Frontier models still matter for the hardest cases, with premium models still capturing a large share of total dollars spent even as they handle a shrinking share of total work volume.
- A practical eval loop starts with a cheap model, tests it against your standards, and iterates up in cost only when the cheaper option actually fails.
How do you actually build an eval for a business task?
Start with the output you already know how to judge. If you’re generating a strategy document, a support reply, or a code change, you likely already have a sense of what “good enough” looks like because you’ve reviewed that work before. Turn that judgment into a checklist: does the answer resolve the customer’s issue, does the code compile and pass tests, does the document contain the analysis a reader needs to make a decision. That checklist is your eval.
Run the task through a cheap model first. Score the output against your checklist. If it passes consistently, you have evidence, not a hunch, that the inexpensive option is viable. If it fails, note exactly where it falls short. Sometimes the fix is a better prompt or an extra review pass with the same cheap model, which can still be less expensive than jumping straight to a frontier model. Sometimes the gap is real, and that failure is itself useful: it tells you the expensive model’s price is justified for that specific task.
The key discipline is testing the actual job, not a proxy for it. A generic benchmark score tells you how a model performs on someone else’s test set. Your eval tells you how it performs on your work, judged by your standards.
Why does paying for the most capable model often waste money?
Because a lot of business work doesn’t need the capability a frontier model adds. A strategy document is a clear example: it feels like the kind of task that deserves the best reasoning available, yet the most expensive model can produce a genuinely impressive document that doesn’t improve the underlying business decision enough to justify the bill. People have spent hundreds of dollars in API costs on frontier models for exactly this kind of task and come away unsure it was worth doing at all.
The same logic applies to coding and customer support. In support, most incoming questions are routine, and a cheaper model can resolve them reliably at an acceptable cost, while only the genuinely hard cases need the most capable model. Routing tools now exist to send easy cases to cheap models and hard cases to expensive ones automatically. In coding, the useful question isn’t “which model is smarter,” it’s “does this model produce a correct change that works in this codebase with minimal human repair.” A developer and a finance leader can argue endlessly about which model is better; an eval settles whether either one actually meets the bar for the task in front of them.
What does the spending data say about this shift?
 Enterprise-ready
- Self-hosted
- SOC 2
- HIPAA
- Audit log
- Role-based access
Token volumes keep climbing while dollar spend has barely moved. Ramp’s reporting shows two months, August and September, of almost no growth in token spend even as token volumes rose month over month, and its November update put October’s spending growth at roughly 1.65%, essentially flat. Adoption continued to widen (Ramp put it at 56.8% of businesses in its sample), yet aggregate spend growth stayed near zero for three straight months.
That combination, rising usage with flat spend, is what you’d expect if businesses are shifting routine work to cheaper models rather than scaling up spend on the same expensive one. A simple illustration: a company spending $5,000 a month on a billion tokens at $5 per million can move most routine work to a cheaper tier averaging $1 per million, and now run 5 billion tokens for the same $5,000. Consumption grows five times over; supplier revenue doesn’t grow at all. Crucially, that shift doesn’t require switching vendors. A customer can move down a model maker’s own price ladder and keep the relationship while paying less per unit of work.
Frontier models haven’t disappeared from the spending picture. Ramp’s November report found frontier models still accounted for close to 70% of spending, with that share even ticking up slightly in October. Some tasks genuinely justify paying for maximum capability. But a large and growing share of total work volume is going to cheaper tiers, which is why dollar share and work share are starting to diverge.
Is this bad news for AI model makers?
Not necessarily, but it changes where the value in the chain accrues. Falling per-token prices can open new markets entirely: work that wasn’t worth doing at a dollar might be worth doing at ten cents, which is one lesson from how consumer-facing AI tools have expanded usage by cutting price. New capabilities can also create services that didn’t exist before. Labs are also not relying on a single expensive product; they offer ranges of models at a range of price points specifically so customers can match spend to task.
But three straight months of flat spend despite rising adoption and rising usage is a signal worth taking seriously. It suggests better intelligence and wider adoption aren’t automatically sufficient to grow revenue for the model maker. Ramp also reported customers negotiating enterprise contracts from stronger positions, using eval results as evidence a cheaper option is viable even when staying with the same supplier, which pushes discounts into deals that don’t show up as vendor switching. Infosys described a related pressure on an October earnings call: AI revenue was growing quickly, but customers were simultaneously demanding that AI-driven productivity gains be passed through in pricing, compressing margin even as volume rose.
How should a business actually use this when buying AI?
Treat model selection as a procurement decision backed by evidence, not a technical debate about which model is smarter. Pick a reasonably cheap model as your default starting point. Build evals around the specific tasks you’re paying for. Test the cheap model against those evals before approving spend on anything more expensive. When a new model ships, from any vendor, run the same evals on it rather than assuming it belongs at the top of your stack by reputation.

A big announcement for MindStudio builders
- 11:30am PT · 2:30pm ET · 1 hour
- Live on Zoom · with Q&A
Expect your own customers to apply the same logic back to you. If your business sells AI-driven services, your buyers will increasingly ask for evidence that the capability they’re paying for is actually necessary for the outcome they want, the same way you’re asking it of your model vendor.
Frequently Asked Questions
What exactly is an AI eval?
An eval is a structured test that runs a specific task through a model and scores the output against a defined standard of acceptable quality, built around the real work a business needs done rather than a general-purpose benchmark.
How do I know if a cheaper model is “good enough”?
Run your actual task through it and score the output against the standard you’d apply to a human doing the same work. If it consistently passes, treat that as evidence the cheaper model meets your requirement, not just a guess based on a model’s reputation.
Does switching to a cheaper model mean switching AI vendors?
No. Most model makers offer multiple tiers at different prices, so a business can often move to a cheaper model from the same provider and keep its existing contract and relationship while reducing cost per token.
Why are frontier models still getting a large share of AI spending if cheaper models work for most tasks?
Some tasks genuinely require more capability and justify the extra cost, and those tasks still consume a large share of total dollars even though they represent a shrinking share of total task volume as cheaper models absorb more routine work.
What should I do when a new, more expensive model is released?
Run it through the same evals you already use rather than assuming it’s automatically worth adopting. If it doesn’t clear your bar by a meaningful margin over your current model, there’s little reason to pay the premium.