How to Build an AI Model Router with Jev and Open Jev
Learn how to build a local AI model router that uses Jev-style classifiers to gate, categorize, and route prompts between local and cloud models.
What is a Jev-style model router?
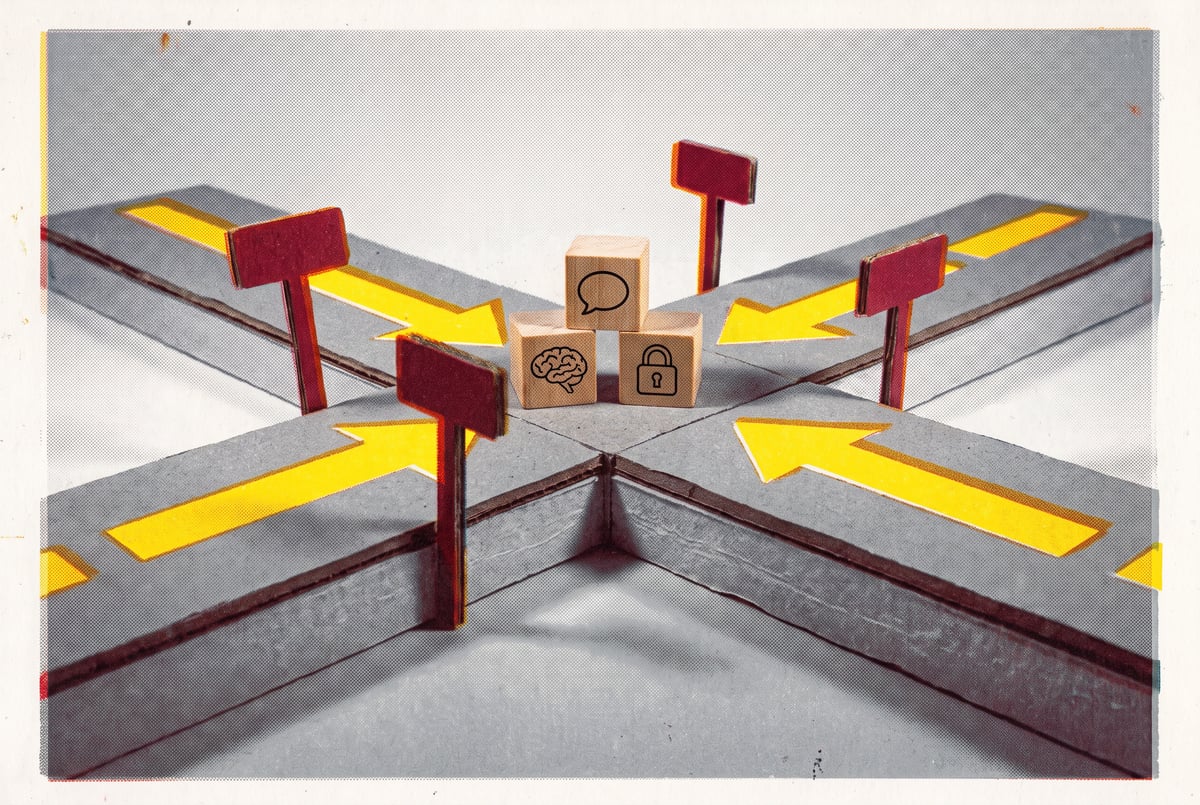
A Jev-style model router is a local service that inspects every prompt before it reaches a language model, classifies it along a few dimensions (task type, difficulty, privacy risk), and then sends it to whichever model fits best. Jev, from Typesafe AI, is built for exactly this: it’s a “system one” classifier that doesn’t generate text at all. You give it a state (the thing to judge) and a set of typed questions, and it returns typed answers with probabilities attached. That output becomes the conditional logic your router runs on, instead of trying to parse loose JSON out of a chatty LLM.
TL;DR
- Jev is a classifier, not a generator, returning typed answers (choice, score, or null) with probabilities so your code can branch on them like an if-statement that understands language.
- Three question types cover most routing needs: choice for categorizing task type, score for rating difficulty on an ordered scale, and null for yes/no gates like detecting private data.
- A single Jev call can ask multiple questions in parallel against the same input, so classifying task type, difficulty, and privacy risk together costs roughly the same latency as asking one question.
- Confidence scores let the router fall back safely when Jev isn’t sure, instead of guessing and sending a prompt somewhere it shouldn’t go.
- The demoed architecture pairs a small local model (MiniCPM 5 2B) with a cloud model (Deepseek V4.1 Flash) and a local image model (Qwen Image 2.1), picking a lane based on Jev’s classification.
- Sending prompts to a hosted classifier like Jev for a privacy check has an inherent leak problem, which is why swapping in a self-hosted “Open Jev” clone matters if you want the whole pipeline to stay on your machine.
- The whole system runs as a small stack: a browser UI, a FastAPI backend that calls Jev and the model endpoints, a routing rules layer, and SQLite for logging decisions and messages.
Remy is new. The platform isn't.
Remy is the latest expression of years of platform work. Not a hastily wrapped LLM.

How does the classification step work?
Jev supports three question types, and each one maps to a specific job in a router.
Choice questions give Jev a state and a list of categories, and it returns a probability for each option plus a confidence value. This is the categorization step: is the incoming prompt chitchat, a simple question, a rewrite or summarize task, code, reasoning or analysis, or an image request? Whatever category wins becomes the “lane” the request travels down.
Score questions ask Jev to place the input on an ordered scale, up to ten levels, again with a confidence value attached. In a router, this answers “how hard is this task?” A trivial score means a small local model can handle it. A score near the top of the scale means the request needs a frontier-grade model.
Null questions are binary: yes or no, true or false, with a probability attached to the “yes” side (so you get the “no” probability for free by inverting it). This is the gate mechanism. The clearest example is detecting personally identifiable information (PII) or client-confidential data, things like API keys, passwords, financial or medical details. If that gate fires, the router forces the request to stay local regardless of what the difficulty or category classification says.
All three questions can be sent in a single call against the same state, and Jev evaluates them in parallel. That means asking three things costs about the same latency as asking one, which matters when the classification step sits in the critical path before any actual generation happens.
Why does confidence matter for routing decisions?
Every Jev answer comes back with a confidence value, not just a raw classification. That’s the piece that keeps a router from making bad calls on ambiguous input. If Jev is highly confident a prompt is chitchat, the router can send it straight to a small local model without hesitation. If confidence is low, the router doesn’t have to guess: it can fall back to a safe default, such as routing to a more capable model or treating the request as though it might contain private data until proven otherwise.
This is also what makes Jev distinct from just prompting a general LLM to “classify this and return JSON.” A generative model can hallucinate a category or return malformed structure. A classifier like Jev returns typed, probabilistic answers designed to be consumed by conditional logic, which removes an entire class of parsing and reliability problems from the router.
How do you architect the actual router?
The build described in the demo uses a fairly small stack:
- A frontend UI (built as a Next.js app) where prompts get typed and responses stream back.
- A FastAPI backend running locally, which handles the decision-and-routing logic in a single call path.
- Model endpoints that follow the standard OpenAI-compatible API format, which is what lets the same router logic talk to Jev, to a local model server, and to a cloud provider without custom glue code for each.
- SQLite for logging Jev’s decisions, the message history, and even generated images, so every routing decision is auditable after the fact.
- Health checks and fallbacks, so if a preferred model in a lane is unavailable, the router has a defined order of preference to fall through.
Plans first. Then code.
Remy writes the spec, manages the build, and ships the app.
The flow: a prompt comes in, the backend calls Jev with the state and the three question types (choice, score, null), Jev returns its typed answers with probabilities, and the backend applies a small set of rules to pick a lane. Examples of the kind of rules used: if the difficulty score is high, route to a stronger model or a web-enabled one; if the prompt is very long (in the tens of thousands of tokens), route to a general-purpose model; if the privacy probability is above a threshold, force local regardless of everything else.
In the demo setup, the local model was MiniCPM 5 2B (a small, fast model good for trivial chitchat and light edits), the cloud model was Deepseek V4.1 Flash accessed through OpenRouter, and a local image model, Qwen Image 2.1, handled generation and editing requests. Heavier cloud options, like Claude Opus, could be toggled on for cases the router scores as needing top-tier reasoning.
What are the tradeoffs and open problems?
The most immediate issue with using a hosted classifier like Jev for a privacy gate is a paradox: to ask “does this contain private data?” you have to send the data to the classifier first. If the goal is to keep sensitive prompts fully local, routing that same prompt to an external Jev endpoint before the privacy check completes technically already exposes it. In the demoed build, this was treated as an acceptable early tradeoff (trusting Jev’s own handling of the classification call, even while distrusting frontier model providers with the full prompt).
The stated fix is to swap Jev for a self-hosted “Open Jev” clone, an open-source implementation of the same choice/score/null classification pattern, running entirely on local hardware. That closes the loop: nothing, including the privacy check itself, leaves the machine.
Cost and speed are the other practical considerations. Jev-style classifiers are built to be cheap and fast, charging only for input tokens and returning answers quickly, which is what makes it viable to run a classification step in front of every single prompt without adding meaningful latency or expense. A generative model doing the same job, with a full prompt-and-parse round trip, would be slower and more expensive per call.
Is building a model router like this worth it?
For anyone running a mix of local and cloud models, a classifier-driven router solves a real problem: manually deciding, prompt by prompt, whether something needs a frontier model or can be handled by a small local one. Automating that decision with fast, cheap, structured classification (rather than another LLM call) keeps the routing overhead small while still giving you control through explicit rules (difficulty thresholds, token length limits, privacy gates). The main setup cost is building the rules layer and defining your lanes and model preferences, which is a one-time architectural decision rather than ongoing overhead.
Frequently Asked Questions
What is Jev used for in an AI pipeline?
Jev is used as a fast, cheap classification layer that judges a prompt (or any input) against typed questions, choice, score, or null, and returns probabilistic answers your code can branch on, without generating any text itself.
What’s the difference between Jev and an Open Jev clone?
Jev is a hosted service from Typesafe AI. Open Jev clones are open-source implementations of the same choice/score/null classification approach that you can self-host, which matters if you need the entire pipeline, including privacy checks, to stay off external servers.
Why use a classifier instead of just prompting an LLM to categorize text?
Built like a system. Not vibe-coded.
Remy manages the project — every layer architected, not stitched together at the last second.
A classifier returns typed, probabilistic answers designed for conditional logic, avoiding the risk of malformed JSON or inconsistent formatting that comes with asking a generative model to self-report a category.
Can a model router detect private or sensitive data automatically?
Yes. A null-type question asking whether input contains personal, confidential, financial, or credential data can act as a gate that forces a request to stay on a local model rather than being sent to a cloud provider.
Do you need separate calls for categorizing, scoring difficulty, and checking privacy?
No. Multiple question types can be sent in one request against the same input and evaluated in parallel, so the added latency for asking several questions at once is roughly the same as asking just one.