What Is Dream RSI? Google's Recursive Self-Improvement, Explained
Google's Dream RSI paper simulates past AI research to find better discovery paths almost for free. Here's how the mechanism actually works.
What is Dream RSI?
Dream RSI is a research approach, described in a paper from Google researchers and academic collaborators, that lets an AI system improve its own strategy for guiding scientific discovery by simulating past research history instead of running new experiments. Rather than testing ideas in the real world, the system “dreams” against a record of experiments that already happened, replaying and recombining that history to find better paths through it. Because the underlying data already exists, most of this exploration costs close to nothing in compute.
TL;DR
- Dream RSI targets a specific bottleneck in AI research: not the experiments themselves, but the decision of which experiments to run next, which is where huge amounts of time and compute get wasted on dead ends.
- The system treats the history of past experiments as an exact simulator, so it can test thousands of alternative exploration strategies against real outcomes without re-running anything.
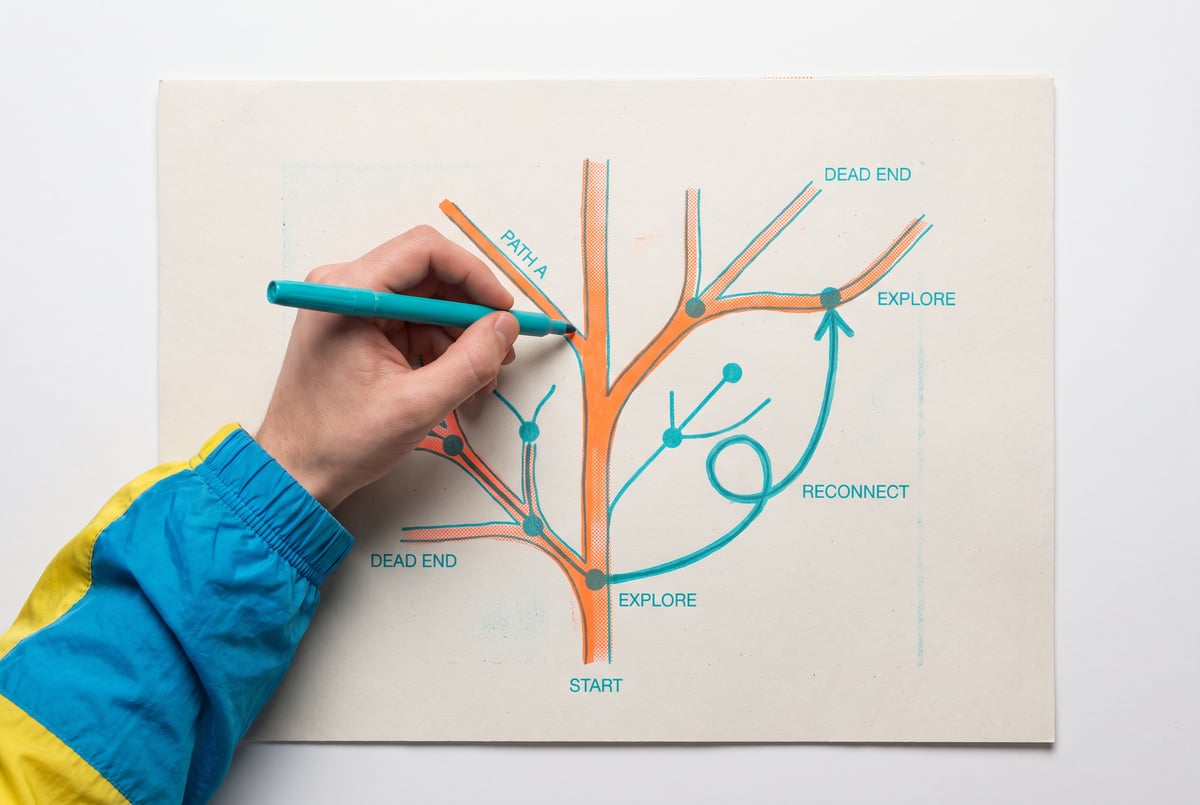
- The mechanism works by rolling back to earlier points in a “discovery tree” and letting a policy explore different branches, learning which paths lead to breakthroughs and which lead nowhere.
- Each successful pass adds a new simulated world to a growing pool, so later policies are trained against more accumulated experience than earlier ones, which is the recursive part of recursive self-improvement.
- In testing, a version called Gemini RSI, built on a Gemini 3.7 Flash model, scored best among the approaches compared, though a related Google system called AlphaEvolve outperformed it on certain mathematical optimization tasks.
- The approach is adaptive, spending less compute when progress is easy and more when the search stalls, and open-ended exploration beat approaches that tried to hint or steer the agent with extra guidance.
- This fits into a broader Google pattern of building tools that optimize the research process itself, following earlier work like AlphaEvolve, which was used to improve real data center scheduling.
One coffee. One working app.
You bring the idea. Remy manages the project.

Why does AI research need something like this at all?
Every research program, human or automated, faces a resource allocation problem. You can run an experiment well and still waste a week of effort because you picked the wrong branch to pursue. Technology history is full of these forks: some ideas looked promising and dead-ended, others looked unpromising and turned into major breakthroughs once the right supporting pieces (better hardware, more data, a missing technique) showed up.
Neural networks are the textbook example. Researchers experimented with them for decades before it became achievable at scale, held back mainly by insufficient computing hardware rather than a bad idea. Once GPUs caught up, the same conceptual approach produced large language models, AlphaGo, AlphaFold, and the current wave of AI systems. The point isn’t that any one person was right or wrong. It’s that deciding where to direct research effort is its own distinct skill, separate from running the experiment correctly, and it’s a skill that’s expensive to learn by trial and error in the real world.
Dream RSI is aimed squarely at that decision-making layer: given a “tech tree” of possible research directions, how do you learn to pick the branches that actually go somewhere, without burning real compute and real time finding out the hard way?
How does Dream RSI actually work?
The core move is treating the record of past experiments as what the paper calls an exact simulator of the search space, not a learned approximation of one. If a research process has already generated a branching tree of attempted experiments, along with which ones succeeded, failed, or led to further discoveries, that tree can answer “what would happen if we tried this path” without anyone needing to try it again. The data already exists as a byproduct of the work that was done.
From there, the system works roughly like this:
- Roll back to an earlier point in the discovery tree, before certain branches were explored.
- Let an exploration policy run forward through that historical world, choosing which experiments to pursue and in what order, entirely in simulation.
- Score how well that policy performed compared to what actually happened historically, or compared to other simulated policies.
- Deploy only the best-performing policy back into the real (or next) discovery process, having tested thousands of candidate strategies at zero real-world execution cost.
- Add the new results as another “world” to the growing pool of simulated histories, so the next round of policy training has more accumulated experience to draw from.
That last step is the recursive part: a policy trained against a larger pool of dreamed worlds tends to outperform one tuned to the luck of a single run, and the new worlds it discovers get folded back into the pool for the next iteration. Each lap makes the simulation richer and the policy that trains on it a little sharper.
What’s the “exploration policy” problem this is trying to fix?
Exploration policy just means the rulebook for deciding what to try next. According to the paper’s framing, that policy is normally handwritten and frozen: a fixed script that grades options and picks the best-scoring one, without ever updating itself based on what it has learned. The problem is that a fixed strategy can’t learn from its own accumulated experience. It keeps paying the cost of directions that have already proven to be dead ends.
Trying to fix this by optimizing the policy live, during an actual discovery run, runs into two walls. First, feedback is delayed and expensive: judging whether an exploration strategy is any good requires watching it steer an entire research run to completion, not just scoring one candidate experiment. Second, the space of possible policies is enormous, and most of the ones you’d have to test along the way are simply bad, wasting real resources to find that out.
Simulating against history sidesteps both problems. Testing a policy against a “dreamed” world returns an answer immediately and costs nothing to execute, since the world it’s testing against was already fully built and paid for as a byproduct of past work.
Is Dream RSI actually better than existing approaches?
In the comparisons described in the paper, Dream RSI was benchmarked against other machine learning approaches, including established optimization libraries, on a lower-is-better scale representing how much resource cost was needed to find good solutions. A version called Gemini RSI, built on a Gemini 3.7 Flash model, produced the best scores among the methods compared. Notably, AlphaEvolve, Google’s earlier evolutionary optimization system, still beat Dream RSI on certain mathematical optimization tasks, suggesting these are complementary tools suited to different kinds of problems rather than one universal replacement for the other.
Two behavioral details stood out. The system is adaptive: when progress is coming easily, it spends less compute, and when the search gets harder, it ramps effort up. And attempts to help the agent by giving it extra guidance or advice based on past actions actually made results worse. Open-ended exploration, letting the policy find its own path through the dreamed worlds rather than nudging it, performed best.
Why does this matter beyond one research paper?
This sits alongside other Google efforts to automate parts of the research process itself. AlphaEvolve, covered when it launched, used large language models to search evolutionary optimization paths and was applied to real infrastructure, improving the scheduling system (Borg) that manages Google’s data centers, producing real measurable savings rather than a purely theoretical result.
The direction these efforts point toward is a division of labor among AI systems themselves: one system focused on running experiments, another focused on deciding what to try next, learning over time which branches of a tech tree are worth pursuing. Dream RSI is a step toward making that second role cheap to train, because it reuses history instead of requiring fresh, costly trial and error every time the strategy needs improving.
Frequently Asked Questions
What does RSI mean in this context?
RSI stands for recursive self-improvement, the idea that an AI system can improve its own capabilities or strategies, which then get used to drive further improvement in a repeating loop.
Does Dream RSI train the AI model itself, or something else?
Based on the paper’s framing, it’s primarily aimed at improving the exploration policy, the decision-making strategy for what experiment or research direction to pursue next, rather than retraining the underlying model’s core capabilities.
Why is simulating history so much cheaper than running new experiments?
Because the record of past experiments already exists as a byproduct of research that was already done. Testing a new strategy against that historical record doesn’t require executing anything new, so it returns results immediately at essentially zero additional compute cost.
How is Dream RSI different from AlphaEvolve?
Both come out of Google’s broader push to automate research decisions, but they target different problems. AlphaEvolve uses evolutionary search guided by language models and has shown strength on mathematical and infrastructure optimization tasks, while Dream RSI focuses on learning better exploration strategies by simulating discovery histories. In the comparisons covered, each outperformed the other on different types of tasks.
Is this the same as training an AI on historical data to predict the future?
Not quite. It’s closer to letting an AI replay and recombine known historical branches to find better strategies within that same space, rather than asking a model to generate entirely new predictions about what happens next in the real world.