How to Build a Personal AI News Digest System with a Coding Skill
Learn how to build an automated AI content engine that filters hundreds of daily sources into one digest using a free Claude Code skill.
What is an AI content engine, and why would you build one?
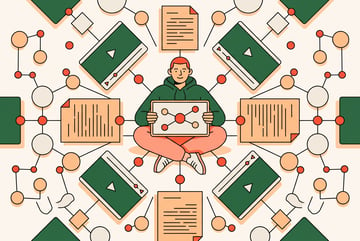
An AI content engine is a personal automation system that pulls in news, posts, and announcements from dozens or hundreds of sources, strips out the noise, and hands you a short daily digest of only the things you actually care about. Instead of manually checking Reddit, YouTube, RSS feeds, Hacker News, GitHub, and changelogs every day, the system does it for you, running the filtering logic in the background and surfacing a concise summary. The core idea is less “track everything” and more “track everything, then aggressively throw most of it away” before it ever reaches you.
This kind of system has become more practical recently because of two things: platforms like Apify that make it easy to pull structured data from sources that used to require fragile scraping or restricted APIs, and cheaper reasoning-capable models (along with tools like Jev) that make it affordable to run lightweight filtering logic on every single item without burning serious money.
TL;DR
- An AI content engine pulls from dozens of sources (RSS, YouTube, Reddit, Hacker News, GitHub, changelogs, archive papers) and filters them down to a daily digest based on your personal interests.
- The system uses a layered filtering approach: deterministic code filters and deduplication first, then a fast cheap pass with Jev, and only the uncertain cases get sent to a full LLM like Claude Haiku.
- Deduplication and stale-content filtering happen before any model call, which keeps token costs low and avoids reprocessing the same announcement twice.
- A real-world run of 864 posts reportedly cost around three cents in Jev calls and 42 cents in Haiku calls, putting the daily cost of the whole pipeline under half a dollar.
- The filtering logic scores content on whether it’s on topic, genuinely new, and concrete rather than a toy demo or low-engagement post, which cuts out a lot of the noise that floods subreddits and blogs.
- A published coding skill can guide a coding agent through building this entire system from scratch, asking you questions about your sources and interests before writing any code.
- All sources and search queries are managed through a single configuration file, making the system easy to extend as you find new things worth tracking.
Seven tools to build an app. Or just Remy.
Editor, preview, AI agents, deploy — all in one tab. Nothing to install.

How does the filtering pipeline actually work?
The system works in stages, and the order matters a lot for cost and accuracy.
Stage 1: Data collection. The engine pulls from a defined list of sources: RSS feeds, YouTube channels, subreddits, Hacker News, GitHub repos, archive paper categories, and product changelogs. Each source can be connected a different way, direct API, a CLI tool, an MCP server, or a platform like Apify that normalizes scraping across many different sites (including ones with restrictive APIs) and returns clean markdown instead of raw HTML or JSON.
Stage 2: Deduplication and deterministic filtering. Before any model touches the data, the system checks a central database to skip anything already seen. It also applies simple code-based rules: drop posts that are too old to be relevant, and drop anything with low engagement (a Hacker News post or YouTube video with only a couple hundred views, for example). This step is intentionally “dumb” and fast. No LLM reasoning is involved yet, which keeps the expensive part of the pipeline from ever seeing content that was never going to matter.
Stage 3: Fast filtering with Jev. Everything that survives deduplication gets evaluated against three criteria: is it on topic, is it something the user would actually care about, and is it genuinely new and concrete rather than a toy demo or rehashed benchmark post. Jev acts as a cheap first-line filter that can make obvious calls instantly, either confidently dropping something as fluff or confidently keeping something because it’s clearly significant (a major model release, for instance).
Stage 4: LLM review for the uncertain middle. Anything Jev can’t confidently classify gets escalated to a full language model (Claude Haiku was the example used), which can reason more deeply and cross-reference a personal memory or interest profile. This is the most expensive step per item, but because the first three stages already filtered out the bulk of the noise, only a small fraction of daily content ever reaches it.
The result is a pipeline that scales to hundreds of sources a day while keeping both cost and reading time low.
Why not just use an LLM for everything?
It’s tempting to skip the deterministic and Jev stages and just throw every post at an LLM. In practice, this was reportedly tried and tested both ways. Running everything through an LLM alone was more expensive, since it meant a model call for every single surviving source rather than just the uncertain ones. More importantly, accuracy actually went down when Jev was used only as a last line of defense instead of a first one: more irrelevant content slipped through, and more relevant content got incorrectly filtered out.
The sweet spot found through iteration was using Jev first for the obvious decisions, obvious keeps and obvious drops, and reserving the LLM for genuinely ambiguous cases. This layered approach mirrors a general pattern worth applying to any high-volume filtering task: push as much work as possible into cheap, deterministic, or lightweight steps, and only pay for expensive reasoning on the content that actually needs it.
How much does running a system like this cost?
Based on one documented run processing 864 posts, the Jev filtering pass cost about three cents, and the subset that escalated to Claude Haiku cost about 42 cents, for a daily total under half a dollar. Actual costs will vary depending on how many sources are being tracked and how much raw text each source produces per run, but the architecture is built around keeping that number small by minimizing how much content ever reaches a paid model call in the first place.
One practical detail worth noting: raw output from an API or scraper is rarely fed straight into a model. Headers, footers, extra whitespace, and other non-informational content get stripped out deterministically first. Platforms that return pre-cleaned markdown reduce the amount of manual cleanup needed here, which also indirectly reduces token costs.
How do you actually build one of these systems?
A published skill (a structured workflow a coding agent can follow) exists specifically to guide a coding agent through constructing this kind of system from scratch, rather than handing over a prebuilt open-source repo to clone and run. The reasoning behind that choice is customization: everyone’s sources and interests differ, so the skill is designed to interview the user first and only then start building.
The process looks like this:
- Install the skill. It can be added as a Claude Code plugin, or pointed at via its repository URL for other coding agents.
- Run it in a fresh folder. A new, empty directory is recommended for building the content engine, though a separate target path can be specified if you want it built inside an existing project or “second brain” setup.
- Answer the interview questions. The skill asks what you need to keep up with, which platforms or tools matter to you, and even prompts for concrete examples, like a time you found out about something late and wish you’d known sooner. This part is meant to take real time (on the order of ten to fifteen minutes) because the quality of the answers directly determines the quality of the filtering later.
- Let it build in phases. Rather than generating the entire system in one shot, the skill walks through a multi-stage build process, testing each stage before moving to the next. This incremental approach is explicitly designed to avoid the kind of half-finished, broken system that tends to result from asking a coding agent to build something this complex in a single pass.
Once built, the system’s day-to-day configuration lives in a single JSON file listing RSS feeds, YouTube channels, GitHub repos, archive categories, and search queries for platforms like Reddit. Adding a new source later just means editing that file rather than touching any pipeline logic.
Is building your own content engine worth it?
One coffee. One working app.
You bring the idea. Remy manages the project.
For anyone trying to track a fast-moving field without reading everything, the tradeoff comes down to setup time versus ongoing time saved. The interview and build process takes a meaningful chunk of time upfront, and tuning the filtering criteria to match personal interests takes longer still (the system described here took over six months of refinement to reach its current accuracy). But the ongoing cost is small, reportedly under a dollar a day, and the daily time saved from not manually checking hundreds of sources can be substantial for anyone whose work depends on staying current with a fast-moving space.
Frequently Asked Questions
What sources can an AI content engine track?
Common sources include RSS feeds, YouTube channels, subreddits, Hacker News, GitHub repositories, product changelogs, and research paper categories on archive. Sources can be connected through direct APIs, CLI tools, MCP servers, or aggregation platforms like Apify that normalize access across many sites at once.
What is Jev’s role in this kind of pipeline?
Jev acts as a cheap, fast first-pass filter that evaluates content against simple criteria (on topic, genuinely new, concrete) before anything reaches a full language model. It handles the obvious keep/drop decisions, which reduces how often the more expensive LLM step needs to run.
Why filter deterministically before using any AI model?
Deduplication and rule-based filters (dropping stale or low-engagement content) are essentially free compared to model calls. Running them first means the AI filtering stages only ever see content that’s already been narrowed down, which keeps both cost and processing time low.
Does this require coding experience to set up?
It requires access to a coding agent (such as Claude Code) that can follow a structured build skill. The skill itself asks plain-language questions about sources and interests, then handles the technical implementation in phases, so deep coding knowledge isn’t strictly required, though comfort with running developer tools helps.
How accurate is the filtering, and does it need tuning?
Filtering accuracy depends heavily on how the criteria are tuned to match personal interests, and it tends to improve over time with real-world use. Removing the LLM step entirely and relying only on lightweight filtering reportedly reduced accuracy significantly, so the layered approach matters for getting reliable results.